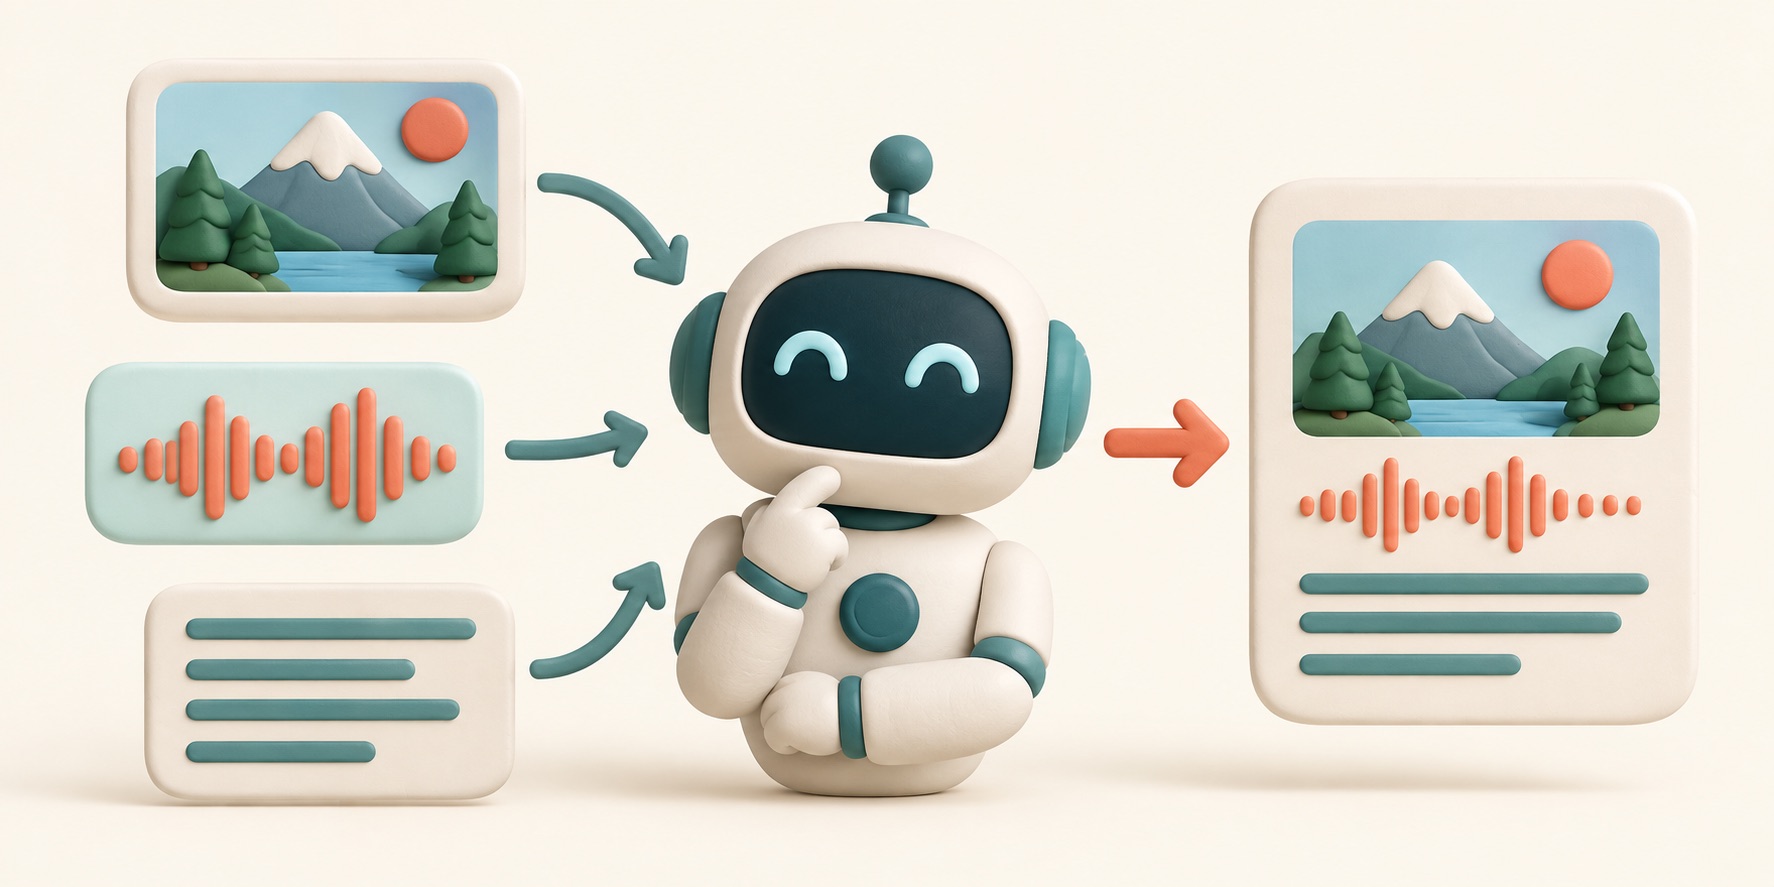
Multimodal AI can work with more than one kind of information, or “mode,” such as written words, pictures, and audio. A regular text-only tool mainly takes in and returns text; a multimodal tool may also describe a photo or respond to spoken words.
For example, you might show an AI a picture of a confusing app screen and ask what the buttons appear to do. It uses the image as part of its input, along with your question.
The AI may still misunderstand what it sees or hears. Check important details yourself, especially when a blurry image or unclear recording could change the answer.